LLM Integration Services
Adding a language model to an existing product is mostly an engineering problem: where the call belongs, what happens when it is slow or fails, what it costs at your volume, and how you know it is still working next month.
Discuss your integration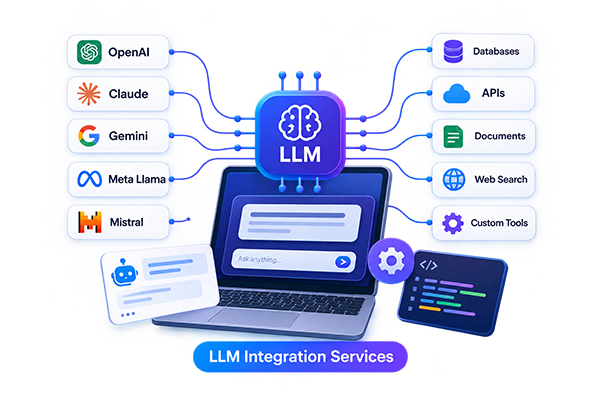
What We Integrate
Language models put to work inside products that already exist.
Summarisation
Long documents, call transcripts and threads condensed reliably, with length and tone under your control.
Classification & Routing
Tickets, emails and documents categorised and routed, with confidence thresholds and human fallback.
Extraction
Structured data pulled from unstructured text into a schema your systems can consume.
Translation & Rewriting
Localisation and tone adaptation with terminology consistency across a whole product.
Conversational Features
Chat interfaces added to existing products, grounded in the data that product already holds.
Structured Output
Reliable JSON and tool calls with schema validation, so downstream systems can trust the shape.
Integration Essentials
Provider abstraction
One interface across providers so switching is a config change, not a project.
Caching
Semantic and exact caching, which on repetitive workloads cuts cost dramatically.
Input and output validation
Schema enforcement and content filtering before anything reaches your systems or your users.
Cost and latency tracking
Per-feature spend and response time, visible from day one rather than discovered on the invoice.
Evaluation
A scored test set so prompt and model changes are verified rather than hoped.
Data handling
PII redaction, retention settings and provider terms configured to your policy.
Where We Put AI To Work
We take on AI projects where the outcome can be measured — a cost that falls, a queue that clears, a decision that gets more accurate.
Talk to our teamAdvanced AI Engineering Capabilities
The difference between a demo that impresses and a system you can rely on.
Evaluation harness
A scored test set built from your real data, run on every prompt, model or retrieval change.
Guardrails
Input and output filtering, prompt-injection defences and refusal behaviour you have chosen.
Cost engineering
Caching, model tiering and context trimming so unit economics work at real volume.
Provider abstraction
One interface across providers, so switching model is configuration rather than a rewrite.
Self-hosted options
Open-weight models served in your own infrastructure where data cannot leave your estate.
Full request logging
Prompt, context, response and score retained for debugging and audit.
How We Deliver
Usually four to eight weeks, depending on how many features are involved.
Assess
Which parts of your product benefit, and what they would cost at your volume.
Prototype and evaluate
Candidate models compared on your data for quality, latency and cost.
Integrate
Built into your codebase with caching, fallbacks and monitoring.
Ship and tune
Released behind a flag, then tuned against real usage.
Add AI Without Breaking What Works
Tell us about your product and where a model might help. We will scope it, cost it and tell you if it is not worth doing.
Talk to our engineersLLM Integration Questions
Everything you need to know about our ai development work.